How we turned WARC files into ZIP archives that anyone can open
If we want more people to use what's in our public web corpus, it needs to be accessible at every level of technical skill. Every month we publish a few hundred terabytes of web captures as WARC files. WARC is a good format to preserve every bit of crawler metadata exactly as it was captured: it is a format for archivists and crawler engineers. A historian who wants the PDFs from a set of government websites, or a linguist who wants only the webpages our language classifier tagged as Swahili, would have to learn a record-oriented container format and a Python library before they could look at a single webpage.
warc2zip fills this gap: given a WARC file (local or remote), it writes ZIP file containing a file for each captured webpage, and additional files with all the metadata (WARC headers, HTTP headers, crawler fields) as CSV files that open in a spreadsheet.
What is in a WARC, and why it is awkward
A WARC file is a sequence of records, each one a block of headers followed by a body, concatenated and usually gzipped one record at a time. One web page capture is not one record. In a Common Crawl WARC it is three: a request record with the HTTP request we sent, a response record with what came back (status line, headers, and body), and a metadata record with what the crawler noticed along the way: fetch time, detected charset, and detected languages. The three are tied together by WARC-Concurrent-To headers, and a warcinfo record at the top of the file says which crawler produced it and when.
To answer a question as simple as "can I see every PDF in this WARC that came back with a status of 200?" (success), you need to read the file record by record, match responses to their requests, parse two layers of headers (WARC and HTTP), look at the Content-Type, and then write the PDF out somewhere. Libraries such as warcio make this a few dozen lines of Python, but a few dozen lines of Python is still a wall for a lot of the people we would like to reach. And you’d have to do extra work to save all of the metadata that goes with the webpage.
There is a second awkwardness that shows up once you leave Common Crawl's own files. WARC 1.1 defines eight record types, and different crawlers use them differently. Heritrix stores DNS lookups as resource records. Browsertrix stores screenshots and page text the same way, and writes no metadata records at all. wget writes its own log into the archive. The pre-2009 ARC format has no record types whatsoever. A tool that only knows Common Crawl's habits will quietly do the wrong thing on everyone else's archives.
What warc2zip does with it
warc2zip streams a WARC file once and writes one ZIP. Inside the ZIP, every response record becomes a file named by a counter with an extension guessed from its Content-Type: 1000000.html, 1000001.pdf, and 1000002.unk when we cannot tell. Everything that is not a body goes into CSV files next to them. Here is the default layout:
CC-MAIN-20260807101845-20260807131845-00000_20261019T101500_a1b2/
  1000000.html
  1000001.pdf
  ...
  manifest.csv                    one row per capture
  manifest.jsonl                  the same, one JSON object per line
  response_http_headers.csv       filename, header_name, header_value
  response_warc_headers.csv
  request_http_headers.csv
  request_warc_headers.csv
  metadata.csv                    the crawler's metadata record, flattened
  warcinfo.csv                    crawl-level provenance
  *_multi.csv                     the same headers, one multiline cell per file
  warcinfo.warc, warcinfo.warc-fields   the warcinfo record, raw bytes
The root directory name is built from the WARC's own filename (see above: CC-MAIN-20260807101845-20260807131845-00000) plus a timestamp (20261019T101500) and a random suffix (a1b2) , so unzipping several archives into the same folder never collides.
- Metadata are provided in two versions.
- Denormalized: the header CSV comes with three columns:
filename,header_name,header_value, one row per header: this meansgrep '"status_code","403"'works, and so does a pivot table. - Multiline: the
*_multi.csvfiles have one row per capture, with all its headers in a single cell, in their original order.
- Denormalized: the header CSV comes with three columns:
- Provenance can be determined for each row. Each
manifest.csvrow carriessource_uri,warc_record_offset, andwarc_record_length. Those three values are enough to re-fetch that one capture with a single HTTP range request, without the ZIP and without reprocessing the WARC. More on why that matters below.
- Sidecar format: groups captures (
--format sidecar) by domain and writes each capture's request, response and metadata headers as small files next to the payload:example.com/1000000.html.response.httpand so on. It is the format for browsing one capture at a time; the flat format above is the one for bulk analysis.
All documentation and examples are provided in the README.
Trying it
To take a quick look at what the ZIP output looks like without having to install warc2zip, please have a look at https://huggingface.co/buckets/commoncrawl/warc2zip-examples.
This 🤗 bucket contains some example input WARCs, and several example ZIP outputs.
warc2zip is available on PyPI. The input can be a local path or a remote resource, including S3, Internet Archive, or HTTP URL:
# We recommend creating a virtual env, e.g.
# uv venv --python 3.12 && source .venv/bin/activate

pip install warc2zip
warc2zip 'https://huggingface.co/buckets/commoncrawl/warc2zip-examples/resolve/500_RECORDS-REPACKAGE-CC-MAIN-2026-30.warc.gz?download=true'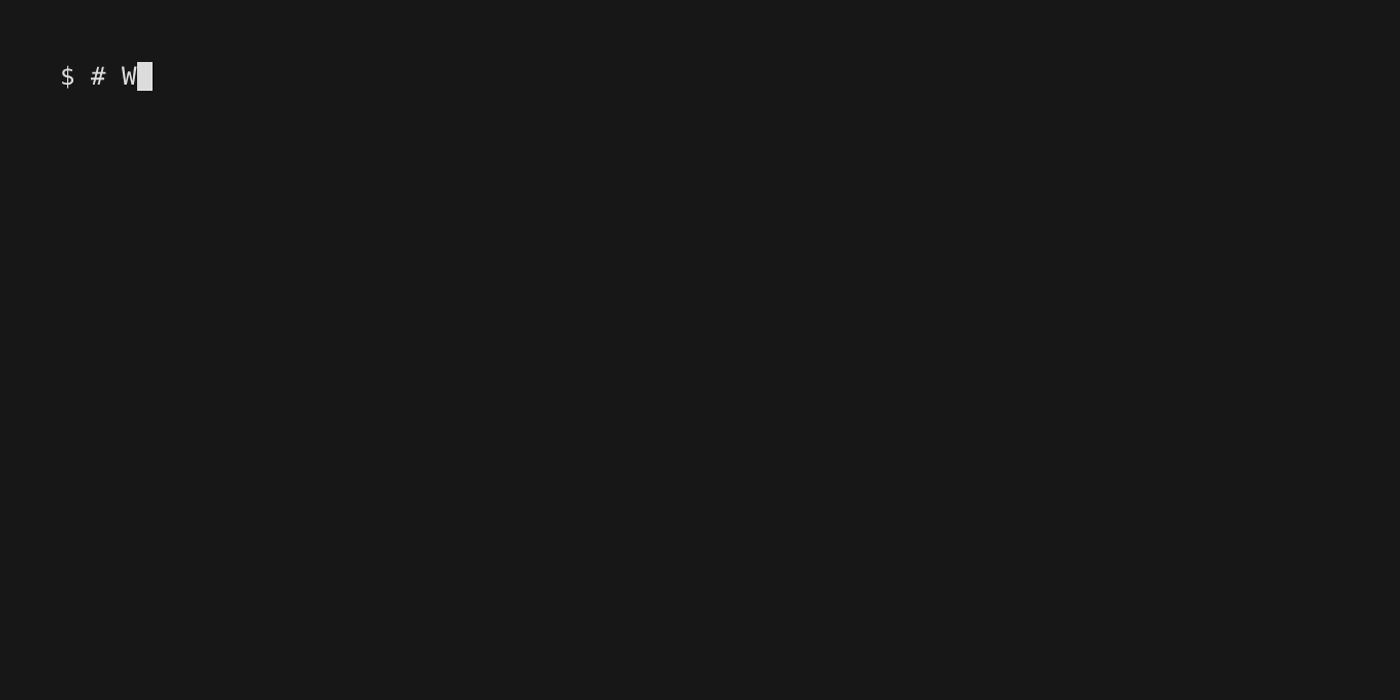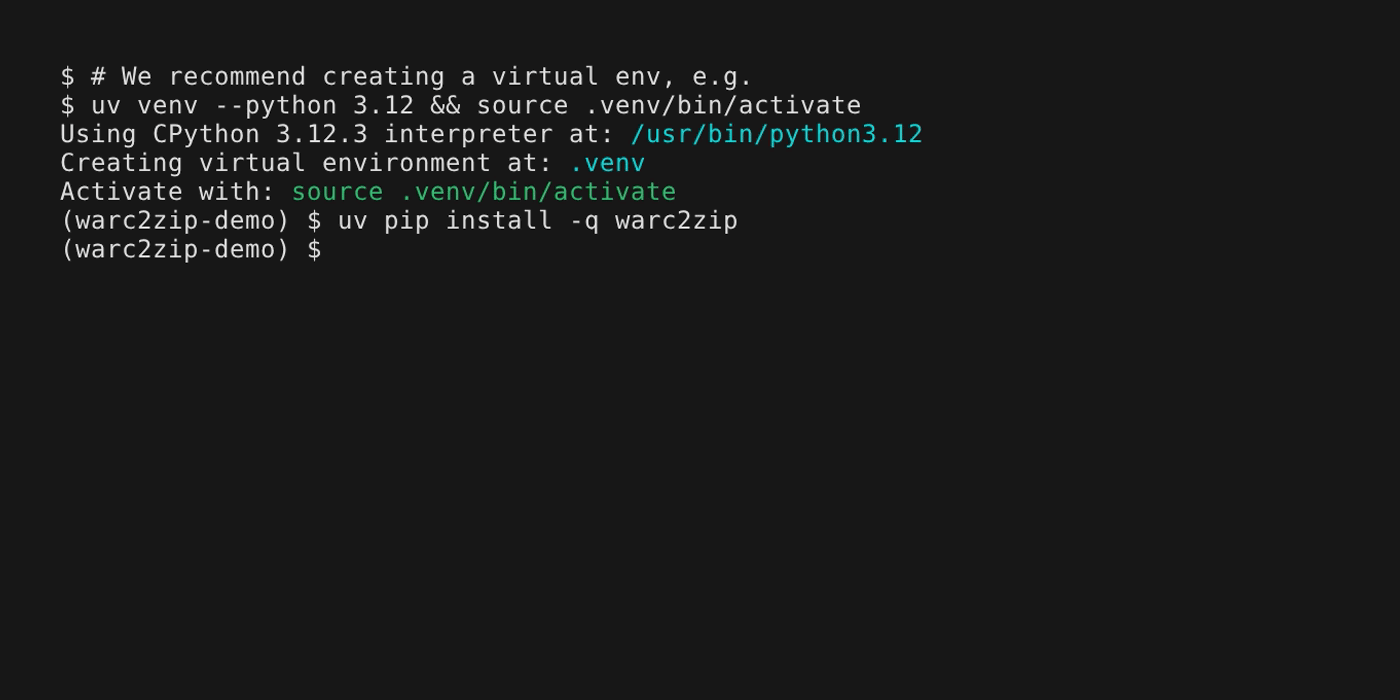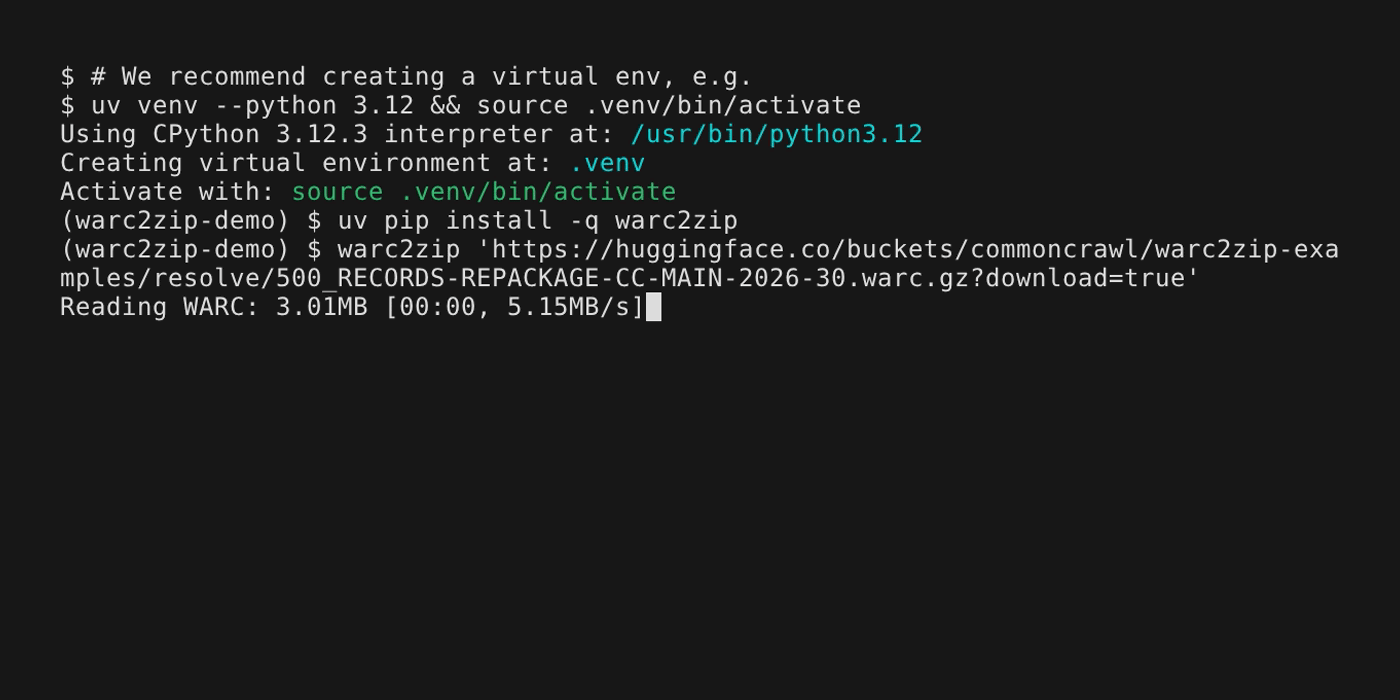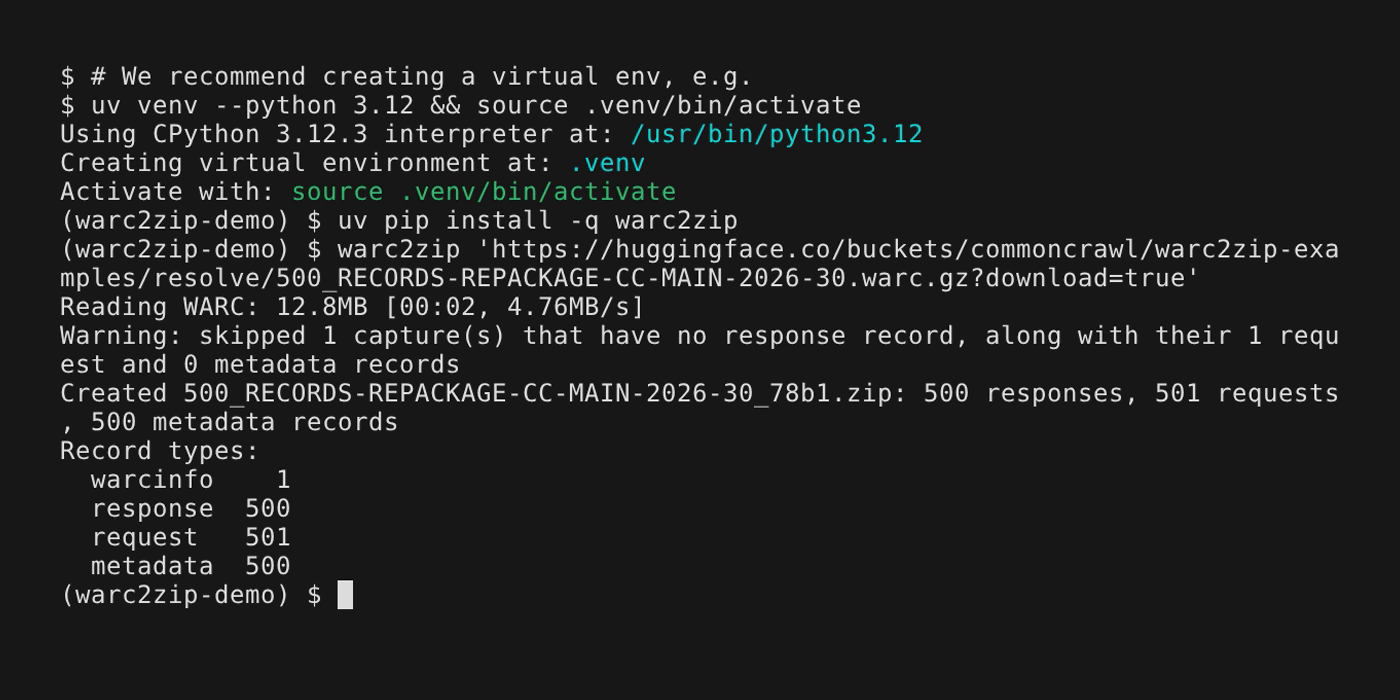
This example is a 13 MB slice of the June 2026 crawl with 500 captures, one of a few test files we make available in https://huggingface.co/buckets/commoncrawl/warc2zip-examples. To explore the ZIP output without having to install the tool, this is where to look.
Every run ends with a summary that accounts for every record in the file:
Created CC-MAIN-20260807101845-20260807131845-00000.zip: 3639 responses, 150 revisits, 3789 requests, 3789 metadata records
Record types:
  warcinfo     1
  response  3639
  revisit    150
  request   3789
  metadata  3789
Record types that were read but not extracted (resource, continuation) still appear in this table, flagged (not extracted). Captures dropped because their response never arrived are counted in a warning on stderr. When a ZIP seems to be missing something, this is where to look.
The workflow we recommend for anything large does not start with the payloads:
- Run with
--metadata-only. The WARC is still streamed end to end, but the ZIP is a few tens of kilobytes of CSV instead of a gigabyte of HTML. - Open
manifest.csvwith whatever tool you already use (a spreadsheet, miller (mlr), a notebook) and keep all of the rows you are interested in, e.g.subset.csv. - Re-run the warc2zip on the same WARC, adding
subset.csvto the command line.
What other people's WARCs taught us
warc2zip has been tested on several WARCs not provided by the Common Crawl Foundation: Heritrix and ArchiveTeam megawarcs from the End of Term 2024 collection, Browsertrix crawls with their separate screenshot and text WARCs, wget output, and ARC files from 2004 and from our own first crawl in 2008.
Following a table with the record type, who produces that, and what warc2zip does with it:
A Browsertrix screenshot is a real capture with a real body, but it has no HTTP layer around it, so it is not a response and the tool skips it. ARC files, oddly, do better here: ARC has no record types, so every ARC record (DNS lookups included) is read as a response and extracted.
We’d love to hear your feedback
warc2zip is on http://github.com/commoncrawl/warc2zip. We provide some examples of WARCs, and their ZIP output. Those are the quickest way to see what the output looks like. Should you have any issues or remarks, please open an issue with a link to the input file, if public.
And if warc2zip lets you look at a corner of the web you could not open before, we would like to hear that too.